Why Is Translation Slow After Connecting to OpenRouter? Top Causes & Fast Fixes 2026
Key Takeaways
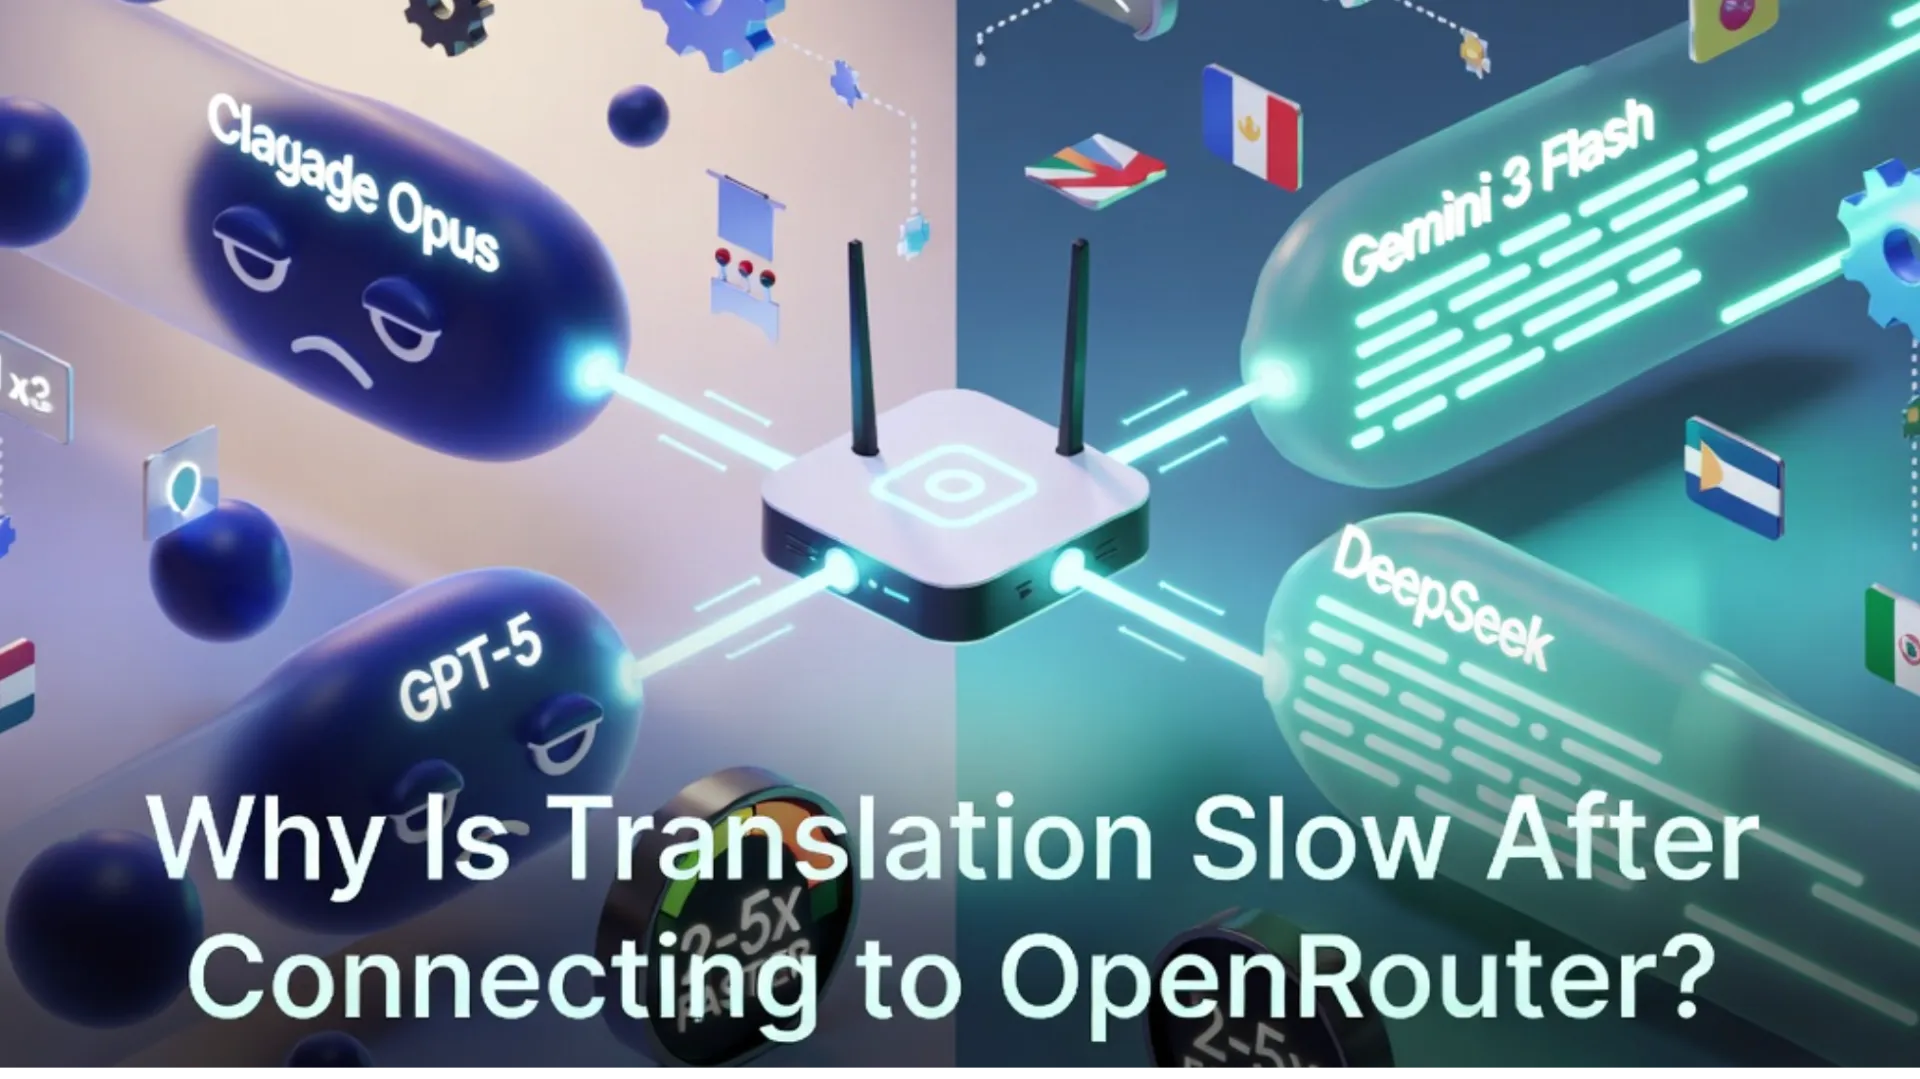
- The #1 cause of slow translation on OpenRouter is using inherently slow models (Claude Opus/Sonnet, GPT-5 class, Gemini Pro) instead of fast ones.
- Default routing prioritizes cost over speed — changing to Latency (lowest first) often delivers immediate improvement.
- Poor batch handling (serial calls, no streaming, long unchunked prompts, high temperature) is extremely common and easy to fix.
- Low credit balance and cold cache on first requests also contribute significantly.
- Switching to fast models like Gemini 3 Flash, DeepSeek V3/V4, Qwen3, or Mistral Small can make translation 2-5x faster while maintaining good quality for most use cases.
Top Causes of Slow Translation on OpenRouter (Ranked by Frequency)
1. Using a Slow Model (Most Common Cause)
Many users connect to OpenRouter and keep using high-quality but slow models:
- Claude Opus / Sonnet 4.x: Best quality, but significantly slower inference, especially on long texts. The longer the context, the more obvious the slowdown.
- Gemini Pro / GPT-5 class models: Excellent quality but suffer from long queues during peak hours.
Fix: Switch to faster models optimized for speed:
- Gemini 3 Flash (or Flash Lite)
- DeepSeek V3 / V4
- Qwen3-235B
- Mistral Small
These models are typically 2-5 times faster on translation tasks and deliver sufficient quality for daily use, documents, visual novels, and most professional work.
2. Default Routing Strategy Not Prioritizing Speed
Even with the same model, OpenRouter has multiple backend providers. By default, it often chooses the cheapest available provider, which may be slower or under heavy load.
Fixes:
- In OpenRouter Dashboard → Settings → Routing, change Default Provider Sort to Latency (lowest first).
- In your API request, add routing parameters:
json { "model": "google/gemini-3-flash", "provider": { "sort": "latency" }, "stream": true }
This forces OpenRouter to pick the fastest available backend for your request.
3. Suboptimal Batch Processing (Very Common)
- Calling translations serially instead of in parallel (no ThreadPool or asyncio)
- Sending very long prompts + full documents in one request without chunking
- High temperature settings (translation works best at temperature=0.2~0.3)
- Not using streaming — the client waits for the entire response before showing anything
Fixes:
- Use parallel processing with asyncio or concurrent.futures
- Split long texts into smaller chunks (500-1500 tokens each)
- Set temperature=0.2 or 0.3 for translation
- Always enable stream=True for much better perceived speed
4. Account, Credit, and Cache Issues
- Very low balance (single-digit dollars) or nearing limits → OpenRouter aggressively clears caches and adds extra checks, slowing every request.
- Peak hours (especially US West Coast evening) cause higher global load on popular providers.
- Cold start on first requests after connecting or long inactivity (caches warm up after a few calls).
Fixes:
- Maintain at least $10–20 balance and enable auto-topup
- Send a few warm-up requests when starting a new session or in a new region
- Avoid running heavy batches during known peak hours if possible
Quick Win Optimization Checklist
- Switch to a fast model (Gemini 3 Flash recommended first)
- Set default routing to Latency priority in dashboard
- Enable streaming + low temperature
- Chunk long texts and use parallel calls
- Keep healthy credit balance
Most users see major speed improvements within minutes after applying the top 2–3 fixes.
Conclusion
Translation slowdown after connecting to OpenRouter is rarely caused by the platform itself. In most cases, it comes down to model choice, routing settings, and batch processing habits.
By switching to faster models and configuring latency-first routing, you can achieve 2-5x faster translation while keeping excellent quality. Start with Gemini 3 Flash and the latency routing change — the difference is usually immediate.
Open your OpenRouter dashboard now, update your default routing settings, and test a fast model on your next translation task. You’ll likely be surprised how much faster it can be.
Continue Reading
More articles connected to the same themes, protocols, and tools.
Referenced Tools
Browse entries that are adjacent to the topics covered in this article.
Hyper3D MCP
MCP ServersHyper3D MCP is Hyper3D's hosted Rodin MCP server for creating 3D assets from natural-language instructions or supported references, checking asynchronous generation progress, and retrieving model download links inside AI coding clients. Official setup is documented for Codex, Claude Code, and Kimi Code CLI.